
Formatting Data Tables in Spreadsheets
Last updated on 2026-10-26 | Edit this page
Overview
Questions
- How do we format data in spreadsheets for effective data use and analysis?
Objectives
- Identify best practices for organizing data to make it
machine-readable
- Recognize and resolve common spreadsheet formatting problems
Data Formatting Principles
It can be tempting to treat spreadsheet programs like lab notebooks, that is, relying on context, notes in the margin, spatial layout of data and fields to convey information. As humans, we can (usually) interpret these things, but computers don’t view information the same way, and unless we explain to the computer what every single thing means (and that can be hard!), it will not be able to see how our data fit together. The goal of a spreadsheet is to balance being human and machine-readable, so there are special organizing principles at play here.
Using the power of computers, we can manage and analyze data in much more effective and faster ways. But to use that power, we have to set up our data for the computer to be able to understand it (and computers are very literal).
This is why it’s extremely important to set up well-formatted tables from the outset - before you even start entering data from your very first preliminary experiment. Data organization is the foundation of your research project. It can make it easier or harder to work with your data throughout your analysis, so it’s worth thinking about when you’re doing your data entry or setting up your experiment. You can set things up in different ways in spreadsheets, but some of these choices can limit your ability to work with the data in other programs or have the you-of-6-months-from-now or your collaborator work with the data.
For this purpose, we are going to introduce a set of principles called “Tidy Data”, with the goal of making data machine-readable and easier to analyze.
Tip
The best layouts/formats (as well as software and interfaces) for data entry and data analysis might be different. It is important to take this into account, and ideally automate the conversion from one to another.
Tidy data in spreadsheets
The tidy data principles when structuring data in spreadsheets are:
- Put all your variables in columns - the thing you’re measuring, like ‘weight’ or ‘temperature’.
- Put each observation in its own row.
- Don’t combine multiple pieces of information in one cell. Sometimes it just seems like one thing, but think if that’s the only way you’ll want to be able to use or sort that data.
- Leave the raw data raw - don’t change it!
- Export the cleaned data to a text-based format like CSV (comma-separated values) format. This ensures that anyone can use the data, and is required by most data repositories.
You can understand these principles more easily with the illustrations in the Tidy Data Series by Lowndes & Horst.
For instance, we’re going to be working with data from a study of agricultural practices among farmers in two countries in eastern sub-Saharan Africa (Mozambique and Tanzania). Researchers conducted interviews with farmers in these countries to collect data on household statistics (e.g., number of household members, number of meals eaten per day, availability of water), farming practices (e.g., water usage), and assets (e.g., number of farm plots, number of livestock). They also recorded the dates and locations of each interview.
If they were to keep track of the data like this:
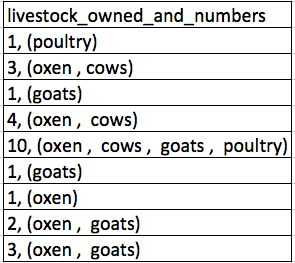
The problem is that the number of livestock and type of livestock are in the same field. So, if they wanted to look at the average number of livestock owned, or the average number of each type of livestock, it would be hard to do. If instead we put the count of each type of livestock in its own column, this would make analysis much easier.
The rule of thumb, when setting up a datasheet, is that each variable (in this case, each type of livestock) should have its own column, each observation should have its own row, and each cell should contain only a single value. Thus, the example above should look like this:
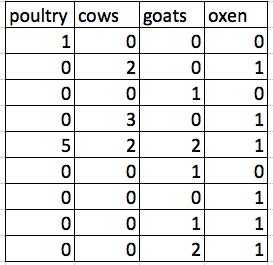
Notice that this now allows us to make statements about the number of each type of animal that a farmer owns, while still allowing us to say things about the total number of livestock. All we need to do is sum the values in each row to find a total. We’ll be learning how to do this computationally and reproducibly later in this workshop.
Handy References
Three excellent references on spreadsheet organization are:
Hadley Wickham, Tidy Data, Vol. 59, Issue 10, Sep 2014, Journal of Statistical Software. http://www.jstatsoft.org/v59/i10
Julia Lowndes & Allison Horst, Tidy Data Series by Lowndes & Horst. https://allisonhorst.com/other-r-fun
Karl W. Broman & Kara H. Woo, Data Organization in Spreadsheets, Vol. 72, Issue 1, 2018, The American Statistician. https://www.tandfonline.com/doi/full/10.1080/00031305.2017.1375989
Keeping track of your analyses
When you’re working with spreadsheets, during data clean up or analyses, it’s very easy to end up with a spreadsheet that looks very different from the one you started with. In order to be able to reproduce your analyses or figure out what you did when Reviewer #3 asks for a different analysis, you should
- create a new file or tab with your cleaned or analyzed data. Don’t modify the original dataset, or you will never know where you started!
- keep track of the steps you took in your clean up or analysis. You should track these steps as you would any step in an experiment. You can do this in another text file, or a good option is to create a new tab in your spreadsheet with your notes. This way the notes and data stay together.
Put these principles in to practice today during the exercises.
Exercise
We’re going to take a messy version of the SAFI data and describe how we would clean it up.
- Download the messy data.
- Open up the data in a spreadsheet program.
- Notice that there are two tabs. Two researchers conducted the interviews, one in Mozambique and the other in Tanzania. They both structured their data tables in a different way. Now, you’re the person in charge of this project and you want to be able to start analyzing the data.
- With the person next to you, identify what is wrong with this spreadsheet. Discuss the steps you would need to take to clean up the two tabs, and to put them all together in one spreadsheet.
Important Do not forget our first piece of advice, to create a new file (or tab) for the cleaned data, never modify your original (raw) data.
After you go through this exercise, we’ll discuss as a group what was wrong with this data and how you would fix it.
- Take about 10 minutes to work on this exercise.
- All the mistakes listed in the next section are present in the messy dataset.
Common Spreadsheet Errors
There are a few potential errors to be on the lookout for in your own data as well as data from collaborators or the Internet. If you are aware of the errors and the possible negative effect on downstream data analysis and result interpretation, it might motivate yourself and your project members to try and avoid them. Making small changes to the way you format your data in spreadsheets can have a great impact on efficiency and reliability when it comes to data cleaning and analysis.
- Using multiple tables
- Using multiple tabs
- Not filling in zeros
- Using problematic null values
- Using formatting to convey information
- Using formatting to make the data sheet look pretty
- Placing comments or units in cells
- Entering more than one piece of information in a cell
- Using problematic field names
- Using special characters in data
Using multiple tables
A common strategy is creating multiple data tables within one spreadsheet. This confuses the computer, so try to avoid doing this! When you create multiple tables within one spreadsheet, you’re drawing false associations between things for the computer, which sees each row as an observation. You’re also potentially using the same field name in multiple places, which will make it harder to clean your data up into a usable form. The example below depicts the problem:
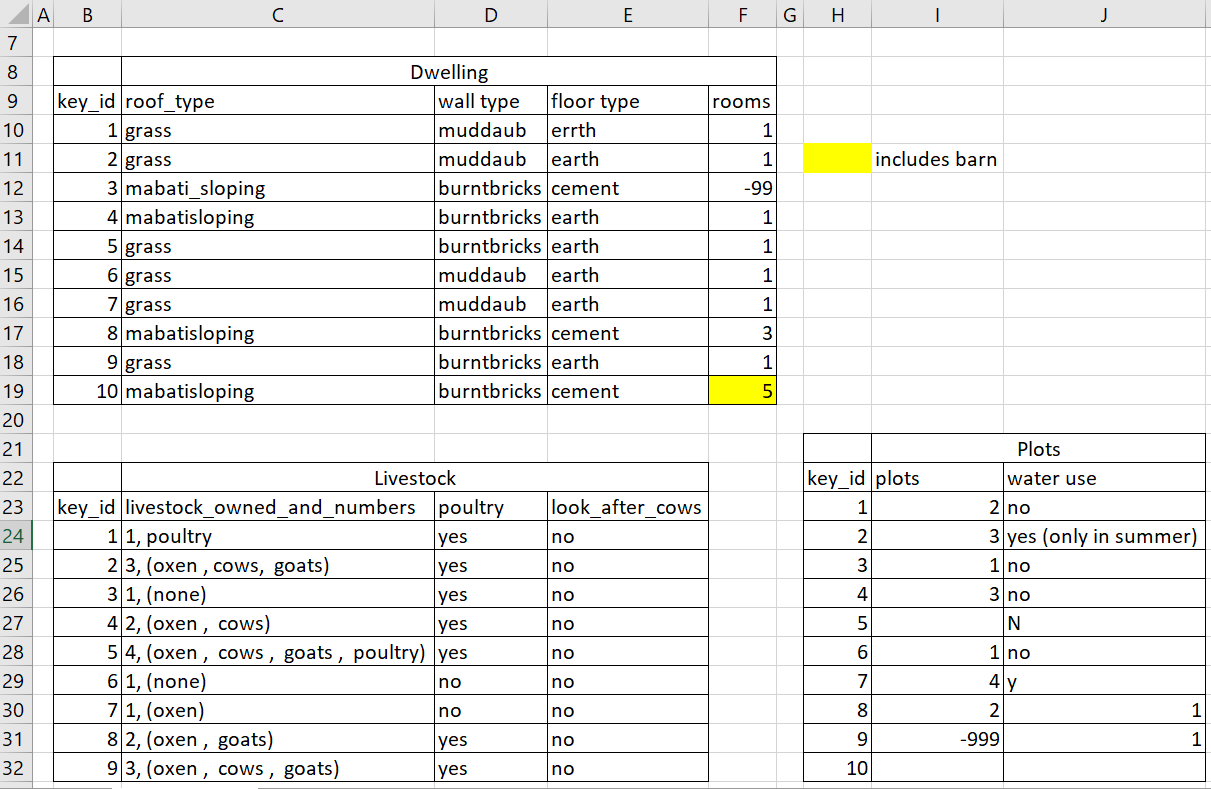
In the example above, the computer will see row 24 and assume that all columns A-J refer to the same observation. This row actually represents two distinct samples (information about livestock for informant 1 and information about plots for informant 2). Other rows are similarly problematic.
Using multiple tabs
But what about workbook tabs? That seems like an easy way to organize data, right? Well, yes and no. When you create extra tabs, you fail to allow the computer to see connections in the data that are there (you have to introduce spreadsheet application-specific functions or scripting to ensure this connection).
Say you make a separate tab for each day you take a measurement. This isn’t good practice for two reasons:
- you are more likely to accidentally add inconsistencies to your data if each time you take a measurement, you start recording data in a new tab, and
- even if you manage to prevent all inconsistencies from creeping in, you will add an extra step for yourself before you analyze the data because you will have to combine these data into a single datatable. You will have to explicitly tell the computer how to combine tabs - and if the tabs are inconsistently formatted, you might even have to do it manually.
For these and other reasons, it is good practice to avoid creating new tabs to organize your spreadsheet data. The next time you’re entering data, and you go to create another tab or table, ask yourself if you could avoid adding this tab by adding another column to your original spreadsheet. You may, however, use a new tab to store notes about your data, such as steps you’ve taken to clean or manipulate your data.
Your data sheet might get very long over the course of the experiment. This makes it harder to enter data if you can’t see your headers at the top of the spreadsheet. But don’t repeat your header row. These can easily get mixed into the data, leading to problems down the road.
Instead you can freeze the column headers so that they remain visible even when you have a spreadsheet with many rows. Read here documentation on how to freeze column headers in Excel and LibreOffice Calc.
Not filling in zeros
It might be that when you’re measuring something, it’s usually a zero, say the number of cows that an informant has, in a region where most farmers have goats and no cows. Why bother writing in the number zero in that column, when it’s mostly zeros?
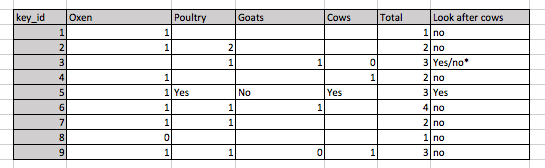
However, there’s a difference between a zero and a blank cell in a spreadsheet. To the computer, a zero is actually data. You measured or counted it. A blank cell means that it wasn’t measured and the computer will interpret it as an unknown value (otherwise known as a null value).
The spreadsheets or statistical programs will likely misinterpret blank cells that you intend to be zeros. By not entering the value of your observation, you are telling your computer to represent that data as unknown or missing (null). This can cause problems with subsequent calculations or analyses. For example, the average of a set of numbers which includes a single null value is always null, because the computer can’t guess the value of the missing observations. Because of this, it’s very important to record zeros as zeros and truly missing data as nulls.
Using problematic null values
Example: using -999 or other numerical values (or zero) to represent missing data.
Solution: One common practice is to record unknown or missing data as -999, 999, or 0. Many statistical programs will not recognize that these are intended to represent missing (null) values. How these values are interpreted will depend on the software you use to analyze your data. It is essential to use a clearly defined and consistent null indicator. Blanks (most applications) and NA (for R) are good choices. White et al., 2013, explain good choices for indicating null values for different software applications in their article: Nine simple ways to make it easier to (re)use your data..
| Null Values | Problems | Compatibility | Recommendation |
|---|---|---|---|
| 0 | Indistinguishable from a true zero | NEVER use | |
| Blank | Hard to distinguish values that are missing from those overlooked on entry. Hard to distinguish blanks from spaces, which behave differently. | R, Python, SQL, Excel | Best option |
| -999, 999 | Not recognized as null by many programs without user input. Can be inadvertently entered into calculations. | Avoid | |
| NA, na | Can also be an abbreviation (e.g., North America), can cause problems with data type (turn a numerical column into a text column). NA is more commonly recognized than na. | R | Good option |
| N/A | An alternate form of NA, but often not compatible with software. | Avoid | |
| NULL | Can cause problems with data type. | SQL | Good option |
| None | Uncommon. Can cause problems with data type. | Python | Avoid |
| No data | Uncommon. Can cause problems with data type, contains a space. | Avoid | |
| Missing | Uncommon. Can cause problems with data type. | Avoid | |
| -, +, . | Uncommon. Can cause problems with data type. | Avoid |
Using formatting to convey information
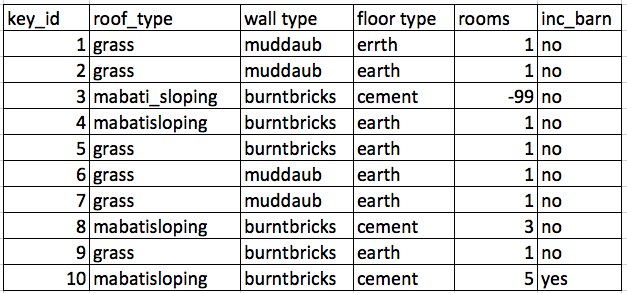
Example: highlighting cells, rows or columns that should be excluded from an analysis, and leaving blank rows to indicate separations in data.
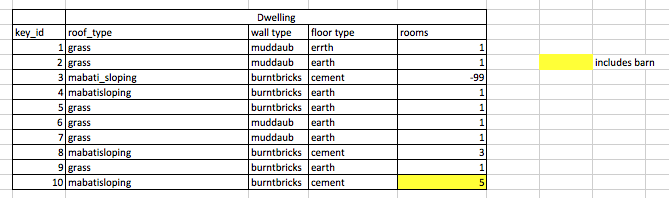
Solution: create a new field to encode which data should be excluded.
Using formatting to make the data sheet look pretty
Example: merging cells.
Solution: If you’re not careful, formatting a worksheet to be more aesthetically pleasing can compromise your computer’s ability to see associations in the data. Merged cells will make your data unreadable by statistics software. Consider restructuring your data in such a way that you will not need to merge cells to organize your data.
Placing comments or units in cells
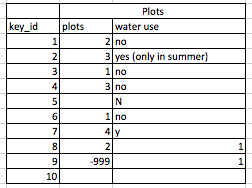
Example: Some of your informants only irrigate their plots at certain times of the year. You’ve added this information as notes directly into the cell with the data.
Solution: Most analysis software can’t see Excel or LibreOffice comments, and would be confused by comments placed within your data cells. As described above for formatting, create another field if you need to add notes to cells. Similarly, don’t include units in cells: ideally, all the measurements you place in one column should be in the same unit, but if for some reason they aren’t, create another field and specify the units the cell is in.
Entering more than one piece of information in a cell
Example: Your informant has multiple livestock of different types. You record this information as “3, (oxen , cows)” to indicate that there are three total livestock, which is a mixture of oxen and cows.
Solution: Don’t include more than one piece of information in a cell. This will limit the ways in which you can analyze your data. If you need both these types of information (the total number of animals and the types), design your data sheet to include this information. For example, include a separate column for each type of livestock.
Using problematic field names
Choose descriptive field names, but be careful not to include spaces, numbers, or special characters of any kind. Spaces can be misinterpreted by parsers that use whitespace as delimiters and some programs don’t like field names that are text strings that start with numbers.
Underscores (_) are a good alternative to spaces.
Consider writing names in camel case (like this: ExampleFileName) to
improve readability. Remember that abbreviations that make sense at the
moment may not be so obvious in 6 months, but don’t overdo it with names
that are excessively long. Including the units in the field names avoids
confusion and enables others to readily interpret your variable names.
Avoid starting variable names with numbers, as this may cause problems
with some analysis software.
Examples:
| Good Name | Good Alternative | Avoid |
|---|---|---|
| wall_type | WallType | wall type |
| longitude | GpsLongitude | gps:Longitude |
| gender | gender | M/F |
| Informant_01 | first_informant | 1st Inf |
| age_18 | years18 | 18years |
Using special characters in data
Example: You treat your spreadsheet program as a word processor when writing notes, for example copying data directly from Word or other applications.
Solution: This is a common strategy. For example, when writing longer text in a cell, people often include line breaks, em-dashes, etc in their spreadsheet. Also, when copying data in from applications such as Word, formatting and fancy non-standard characters (such as left- and right-aligned quotation marks) are included. When exporting this data into a coding/statistical environment or into a relational database, dangerous things may occur, such as lines being cut in half and encoding errors being thrown.
General best practice is to avoid adding characters such as newlines, tabs, and vertical tabs. In other words, treat a text cell as if it were a simple web form that can only contain text and spaces.
- Never modify your raw data. Always make a copy before making any changes.
- Keep track of all of the steps you take to clean your data.
- Organize your data according to tidy data principles.
- Record metadata in a separate plain text file.
- Avoid using multiple tables within one spreadsheet.
- Avoid spreading data across multiple tabs (but do use a new tab to record data cleaning or manipulations).
- Record zeros as zeros.
- Use an appropriate null value to record missing data.
- Don’t use formatting to convey information or to make your spreadsheet look pretty.
- Place comments in a separate column.
- Record units in column headers.
- Include only one piece of information in a cell.
- Avoid spaces, numbers and special characters in column headers.
- Avoid special characters in your data.